 AI-generated editorial illustration
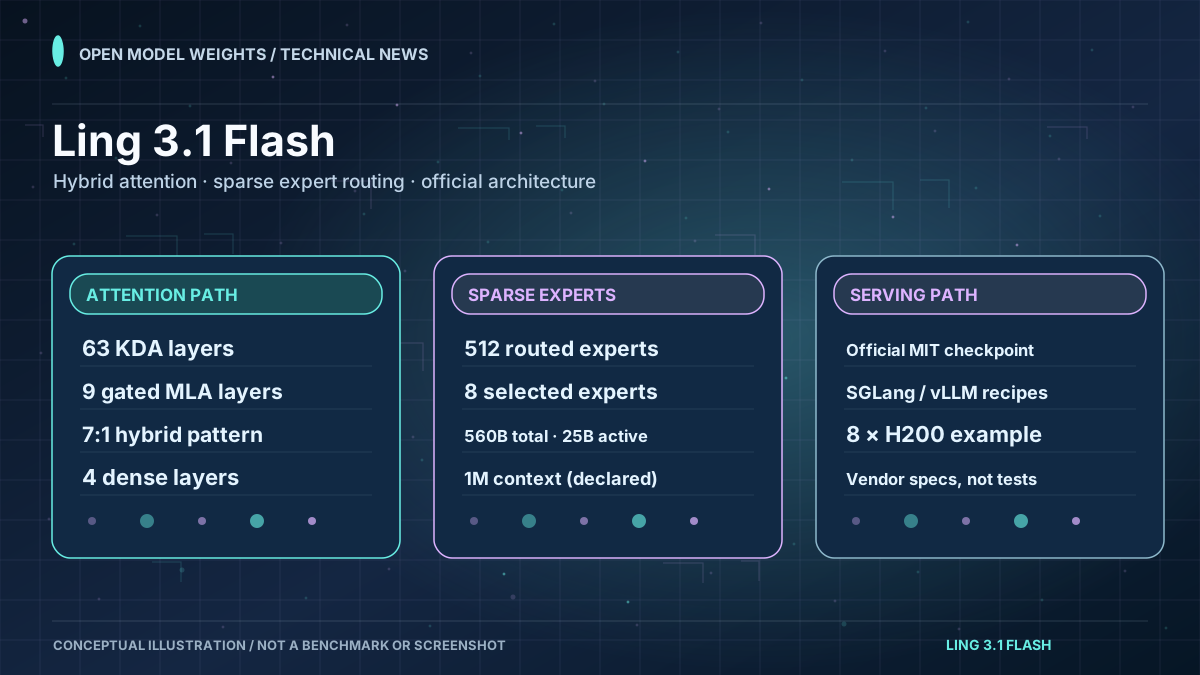
InclusionAI releases Ling 3.1 Flash open weights with 560B hybrid MoE and 1M context
The 560B-total, 25B-active hybrid reasoning model pairs KDA and gated MLA attention with sparse experts; the public MIT checkpoint is aimed at server-scale agent and coding workloads.
Primary sourceInclusionAI official Ling-3.1-flash Hugging Face model card and revision historySource published 2026-10-13
Read evidence brief →