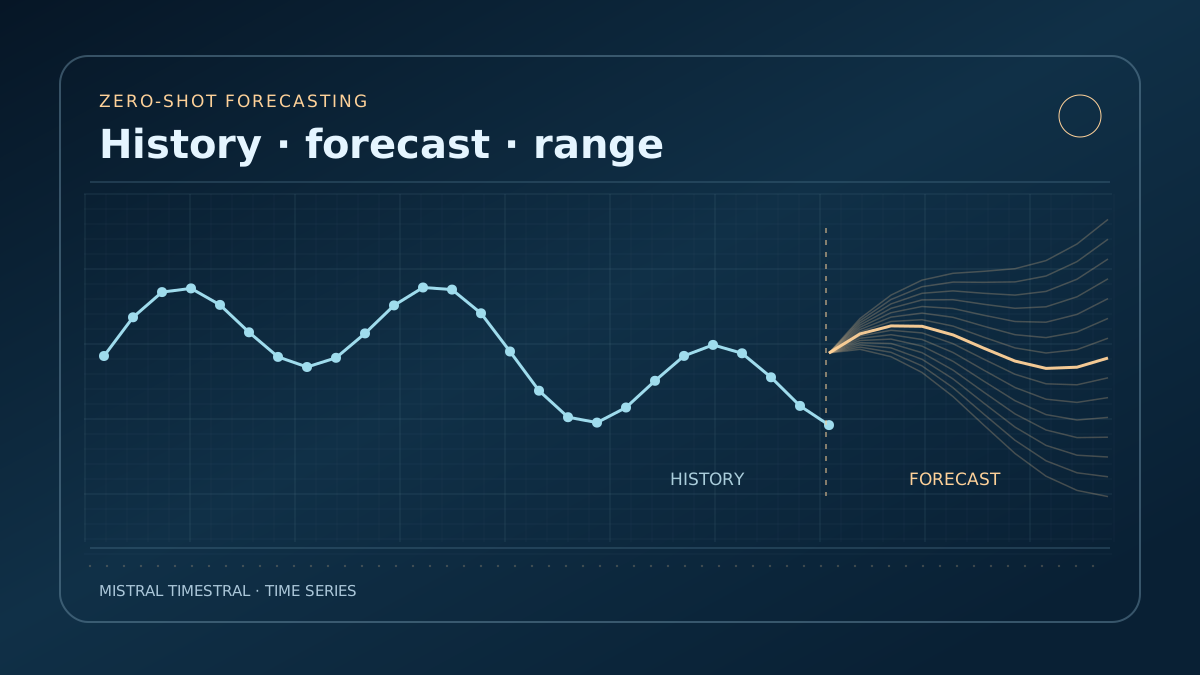
Four small forecasting checkpoints extend the open-weight ecosystem beyond chat models, with benchmark scores and license terms requiring qualification.
Primary sourceMistral AI official Timestral-209M model cardSource published 2026-10-15
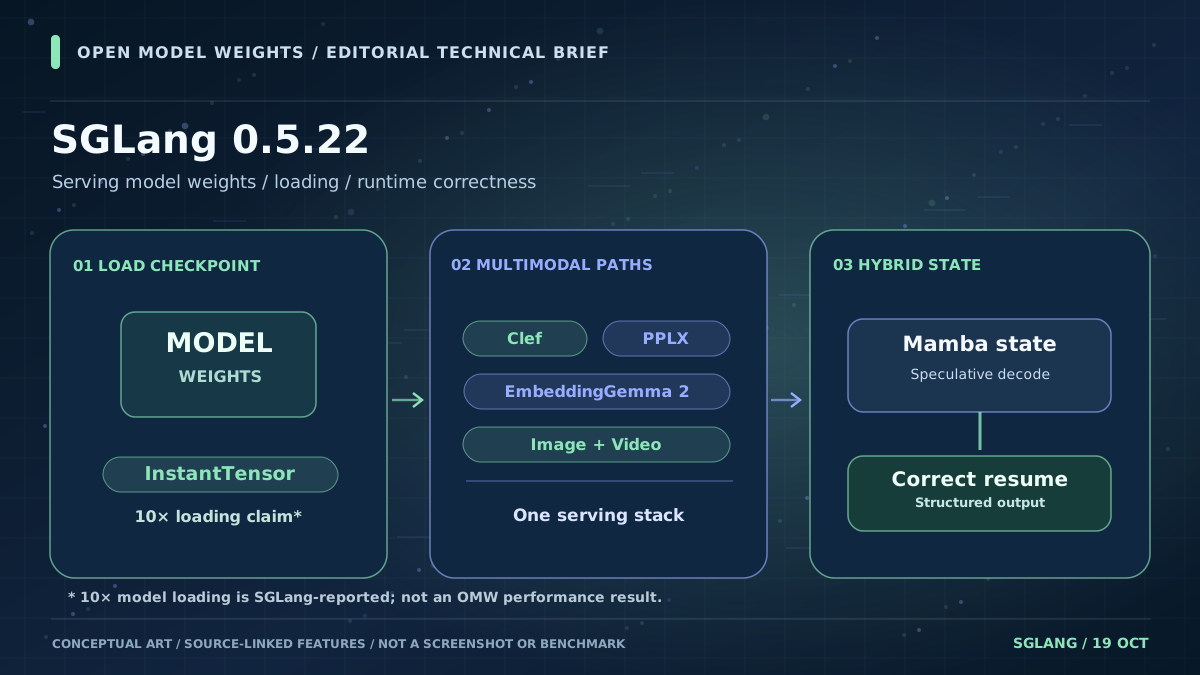
The October 19 serving release advertises a 10x loader improvement and new model integrations; it also fixes a speculative-decoding state error and raises the Python minimum.
Primary sourceSGLang official v0.5.22 GitHub release notesSource published 2026-10-19
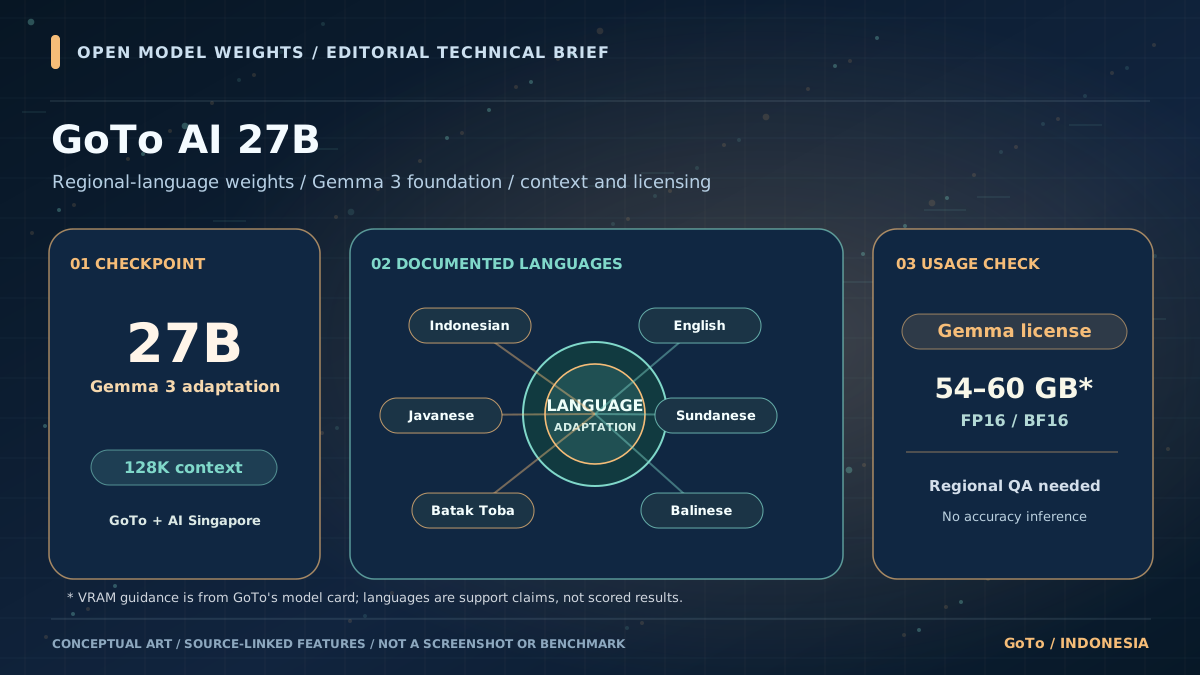
The new GoTo-AI checkpoint targets Indonesian culture and regional-language gaps, but its Gemma terms and full-precision memory footprint need careful reading.
Primary sourceGoTo Group official Gemma 3 27B instruct checkpoint model cardSource published 2026-10-19
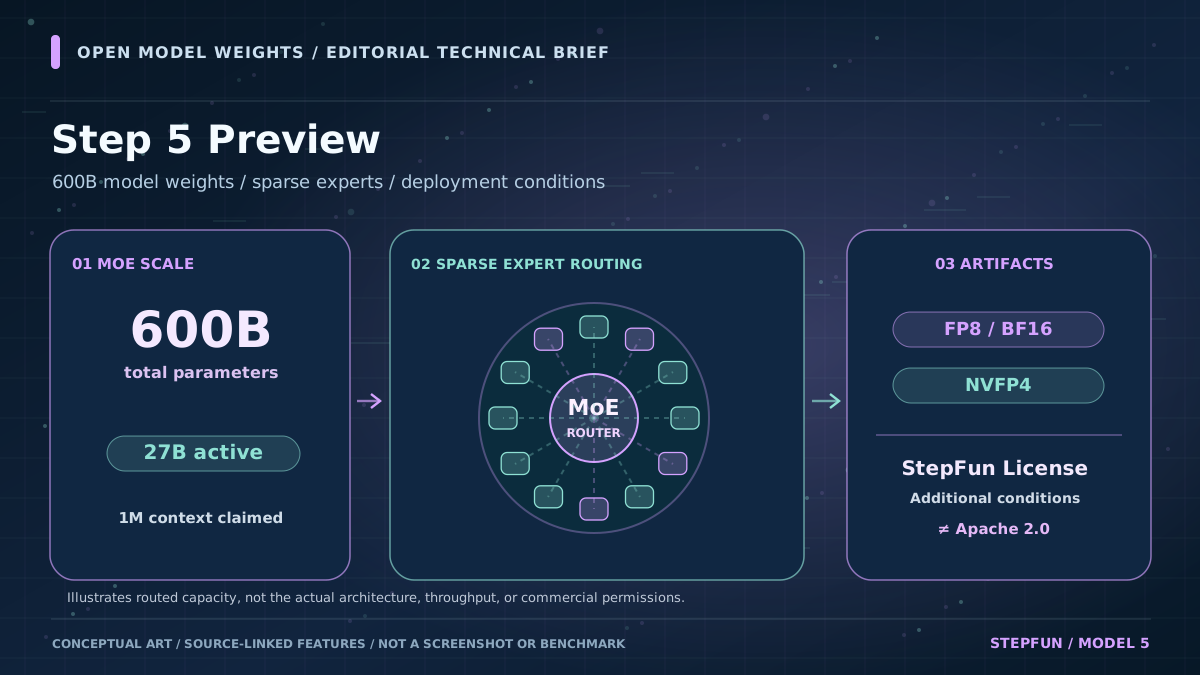
StepFun's downloadable multimodal MoE targets long-horizon agents, but its million-token context claim and Apache-style license language require precise qualification.
Primary sourceStepFun official Step 5 Preview BF16 model card and licenseSource published 2026-10-15
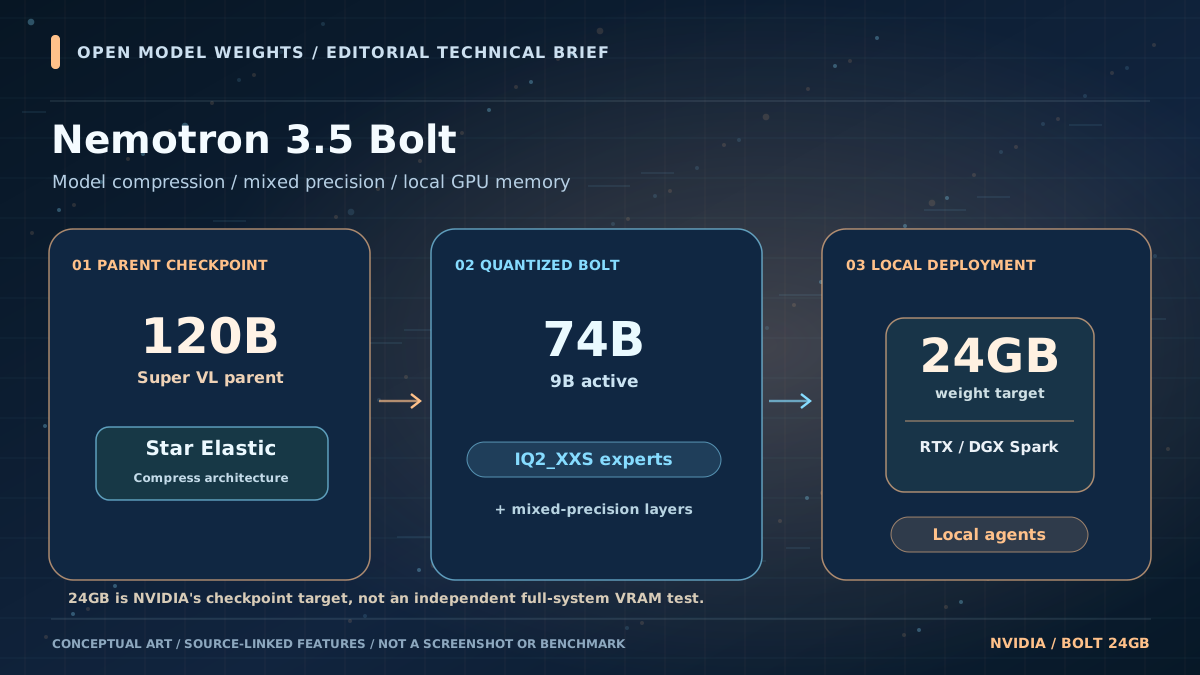
The compact Bolt checkpoint is designed for RTX and DGX Spark with native low-bit weights, while its BF16 sibling serves a different adaptation purpose.
Primary sourceNVIDIA Nemotron 3.5 Bolt 24GB technical report and official model cardSource published 2026-10-15
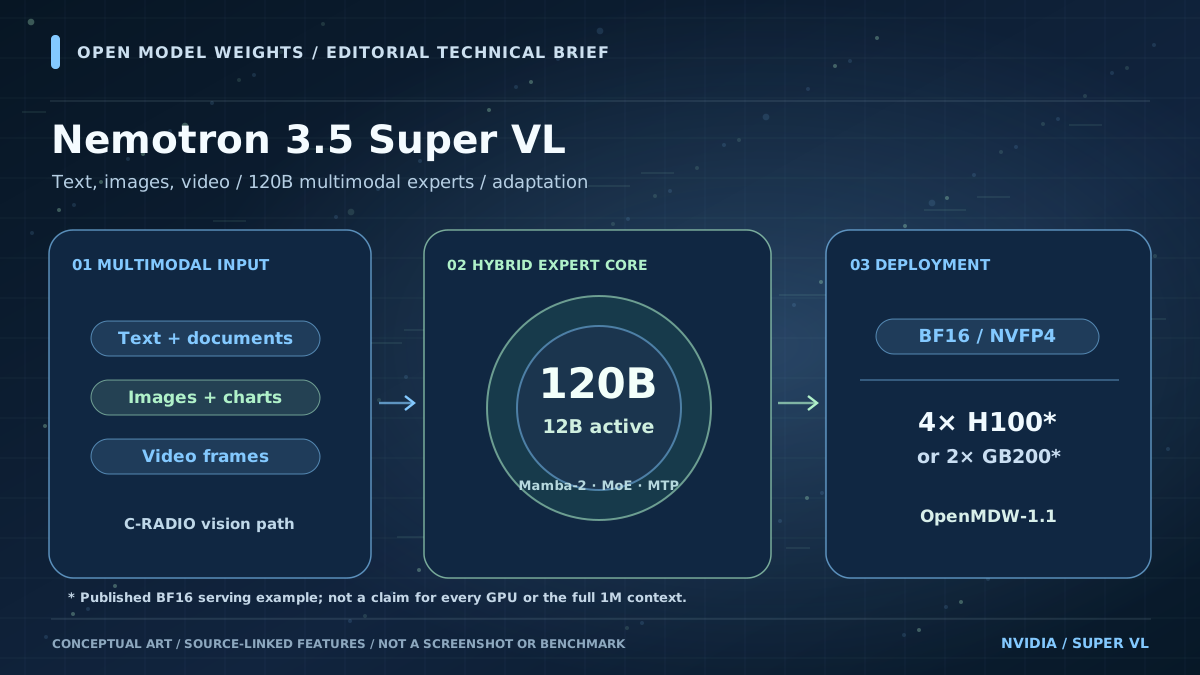
The new 120B-total, 12B-active vision-language parent of Nemotron Bolt targets document-heavy agents and custom training, with model-specific GPU requirements.
Primary sourceNVIDIA official Nemotron 3.5 Super VL BF16 model cardSource published 2026-10-15

 AI-generated editorial illustration