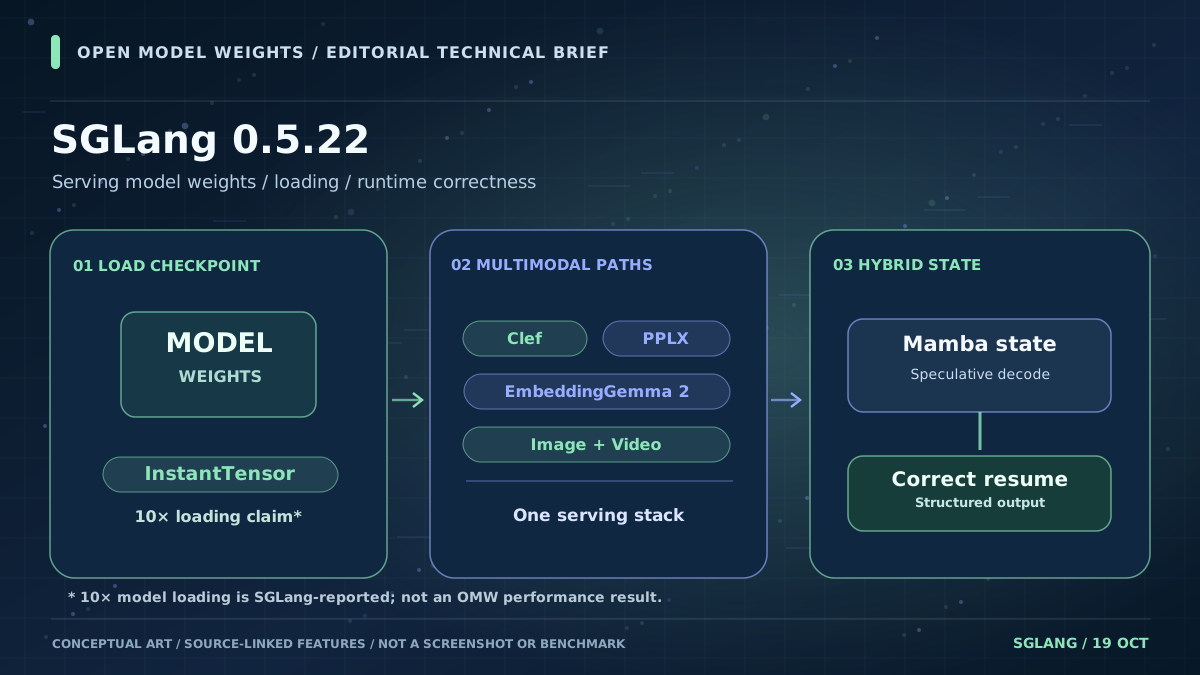
SGLang published version 0.5.22 on October 19 with a wide set of changes for teams serving downloadable AI models. Its release notes bring fresh support for Clef and Clef Flash decision systems, Perplexity's Decider family, Google's EmbeddingGemma 2 and several image and video diffusion checkpoints. These integrations expand where operators can use one serving stack, but support for a model family does not prove that every precision, checkpoint variant or accelerator will work without configuration.
The most concrete operational change is InstantTensor, an optional loading path that SGLang says can load models up to ten times faster in the workloads cited by the maintainers. Other published improvements cover prefill/decode disaggregation and speculative decoding. SGLang attributes up to 2.3-times higher DeepSeek-V4.1 throughput per H200 GPU and separate gains on AMD MI350-series hardware to release-specific optimizations. Those figures are vendor-reported results, not independent Open Model Weights measurements or promises for arbitrary traffic patterns.
There is also a correctness fix that matters more than the headline speed multipliers: some hybrid linear models could resume using incorrect Mamba states when speculative decoding and structured output were combined. Operators using that feature intersection should prioritize regression testing with their real prompts and outputs. The project also adds Apple Silicon support through the standard PyTorch backend alongside MLX, widening local experimentation without implying workstation-class throughput on every Mac.
Compatibility deserves explicit attention. SGLang now requires Python 3.11 or newer; a Python 3.10 installation may silently select an older compatible release instead. Versioned containers are listed for NVIDIA CUDA, AMD ROCm and Intel hardware, but model-specific runtime dependencies still apply. Before production upgrades, pin the exact v0.5.22 image or package, test tool and structured responses, reproduce load-time measurements on your own hardware, and keep a rollback plan. This is a substantial serving update rather than evidence that any underlying model has changed its weights or license.
What this changes for the evidence layer
SGLang 0.5.22 is an inference-server release, not a new verified checkpoint. Its expanded compatibility matrix should prompt deployment-specific smoke tests rather than automated model-registry promotion. Verify each official model's files, access conditions and license independently before adding new records; benchmark ratios are upstream claims only.
SGLang official v0.5.22 GitHub release notes
This brief is based on the cited primary source. Performance, benchmark and comparative claims remain attributed unless Open Model Weights publishes an independent measurement.
Open source article ↗