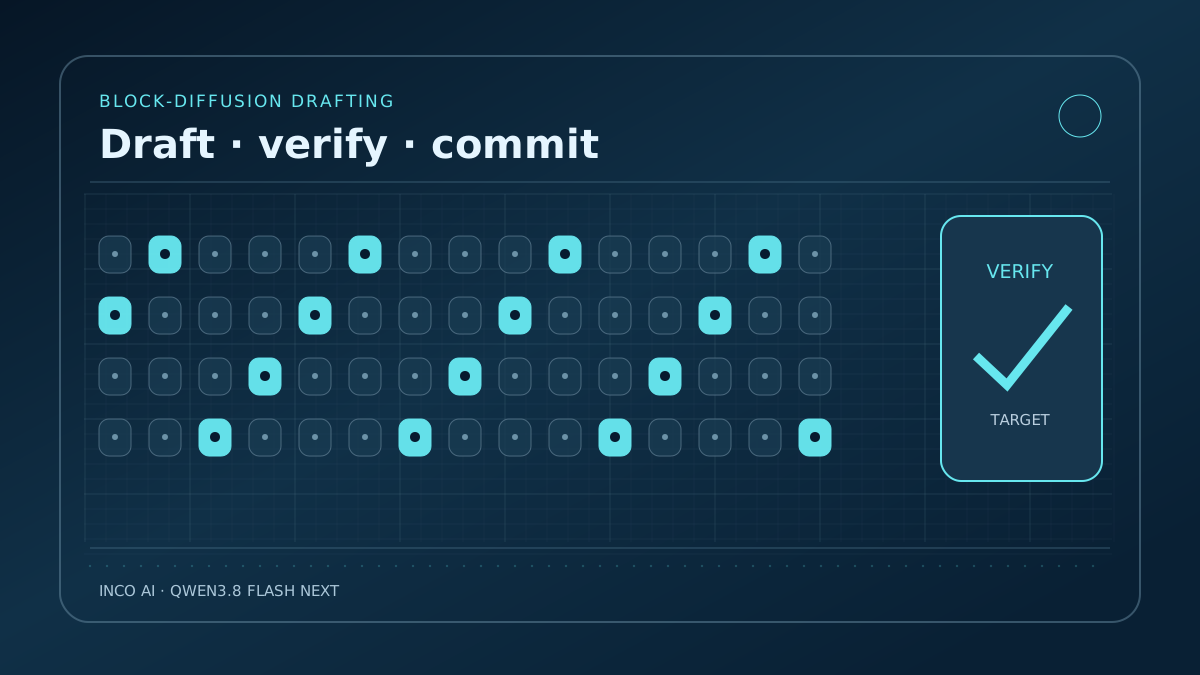
Inco AI has introduced a DFlash 2 draft checkpoint for Alibaba's Qwen3.8 Flash Next family. It is a serving component rather than a new base language model: a small network drafts candidate tokens in advance while the original larger Qwen model verifies them. That distinction matters because a drafter does not independently answer questions or change the target model's reasoning capabilities.
The release extends a block-diffusion approach, where candidate next tokens are predicted in parallel instead of one by one. The publisher's new Flash Next evaluation uses the official FP8 target checkpoint on one NVIDIA GB300 with SGLang. Its reported block size of four permits up to three speculative tokens before the next verification step. This setup is specific; the same throughput cannot simply be assumed for other runtimes or accelerators.
Inco AI reports experiments at low and higher serving concurrency, including eight and 32 simultaneous requests. Acceptance length is not identical to user-perceived latency or aggregate tokens per second. These are publisher-generated figures, not measurements repeated by Open Model Weights. Production teams should pin the matching target and draft revisions, run their actual prompts, and compare memory use and error handling before and after enabling speculation.
The licensing picture also needs care. Qwen's Flash Next target displays Qwen Community License 1.0, while the auxiliary draft checkpoint must be checked independently. An Apache license for a different DFlash 2 model is no substitute for reading this repository's files. Our assessment: this is a useful open-weight inference development for long-running agents, but it proves neither a universal performance multiplier nor an improvement in the target model's accuracy.
What this changes for the evidence layer
News is not independently verified model-registry evidence. Confirm the exact upstream file revisions, license, architecture and source conditions before any model promotion or derived speed and capability claim.
Inco AI official Qwen3.8 Flash Next DFlash 2 checkpoint
This brief is based on the cited primary source. Performance, benchmark and comparative claims remain attributed unless Open Model Weights publishes an independent measurement.
Open source article ↗