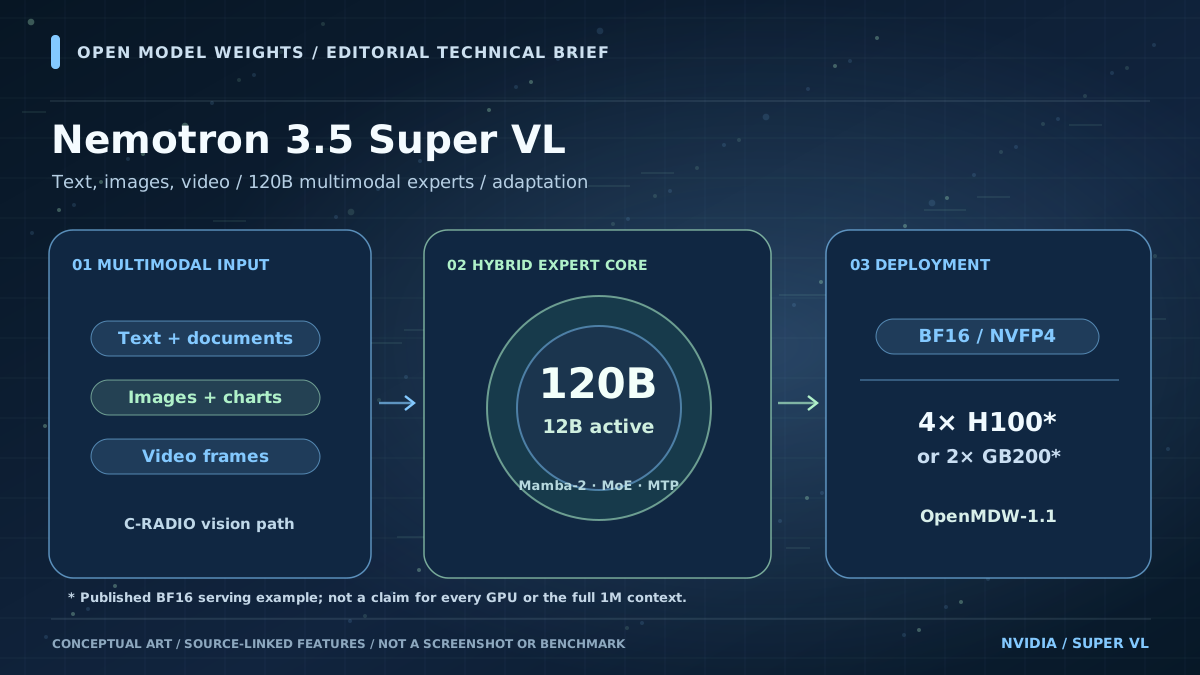
NVIDIA's Nemotron 3.5 Super VL is a newly downloadable 120-billion-parameter vision-language model for document understanding, coding, reasoning and tool-oriented workflows. The official BF16 model card reports 12 billion active parameters in its hybrid Mamba-2, Transformer-attention and mixture-of-experts design, plus a C-RADIO vision encoder. Text, images and video can feed into text responses. Super VL is also the larger source model from which NVIDIA separately compresses its 24GB Bolt release; those are not the same checkpoint with a different label.
Super VL's model card describes up to one million tokens of context and native Multi-Token Prediction for speculative decoding. NVIDIA positions it for visual documents, charts, tables and other material that enterprise agents must read and reason about. It reports strong task performance and high throughput in selected configurations, but those are NVIDIA measurements and test definitions. Open Model Weights has not run a comparable evaluation, verified tool execution, or measured accuracy on private business documents.
The deployment distinction matters. Full-precision BF16 weights are aimed at evaluation, customization and domain adaptation, with an official vLLM example using four H100 accelerators or two GB200s. NVIDIA also publishes an NVFP4 variant for optimized inference on supported hardware. A context-window label is not a promise that serving one million tokens at a useful batch size is practical for every GPU; teams must account for visual preprocessing, activation and cache memory, latency and accelerator-specific kernels.
NVIDIA identifies OpenMDW 1.1 as the governing model license and provides open training and post-training resources for further specialization. Those materials do not convert the weights into Apache 2.0 or automatically verify commercial rights under unrelated licenses. Operators should inspect the exact official revision, trust-remote-code and model-serving requirements, separate publisher benchmark claims from independently reproduced results, and pilot real document and tool tasks before adopting the model. Super VL adds an enterprise-oriented open-weight option, while Bolt's compressed 24GB path solves a substantially different deployment problem.
What this changes for the evidence layer
Inspect Super VL BF16 and NVFP4 as distinct official artifacts under NVIDIA OpenMDW-1.1, verifying the exact commit, weights, vision encoder and input-processing code. NVIDIA's throughput comparisons and one-million-token model limit are attributed claims and do not verify actual runtime capacity. This is related to, but not interchangeable with, the separately published 24GB Bolt derivative.
NVIDIA official Nemotron 3.5 Super VL BF16 model card
This brief is based on the cited primary source. Performance, benchmark and comparative claims remain attributed unless Open Model Weights publishes an independent measurement.
Open source article ↗