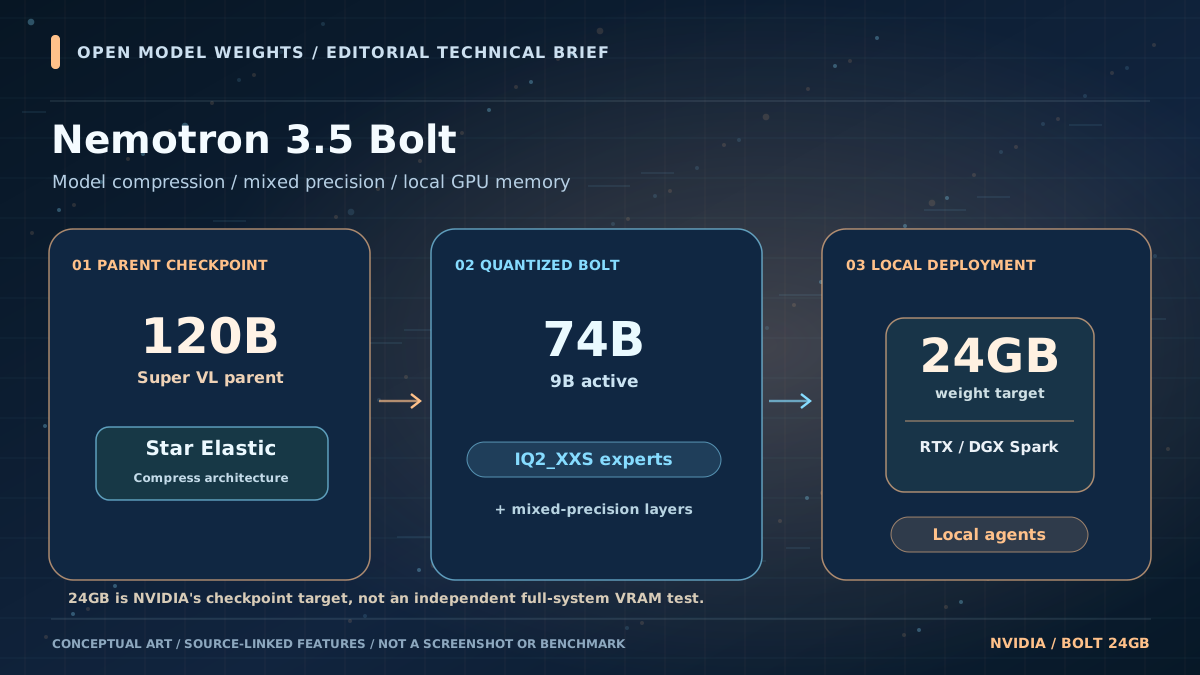
NVIDIA has released Nemotron 3.5 Bolt 74B-A9B 24GB, a downloadable vision-language model aimed at running practical agent workloads on local NVIDIA hardware. The architecture has 74 billion total parameters and nine billion active parameters, combining Mamba-2, Transformer attention, a latent mixture-of-experts system and a vision encoder. The central product distinction is a heavily compressed checkpoint designed to occupy roughly 24GB of model memory, not an ordinary unquantized 74B model.
NVIDIA's technical report explains how Bolt was derived from the larger Nemotron 3.5 Super VL model using its Star Elastic architecture-compression method, followed by additional post-training. Most expert feed-forward weights use IQ2_XXS at about 2.06 bits per element, while other layers retain different precision formats. This mixed quantization is why a simple total-parameter-times-two-bits estimate is insufficient to describe the complete serving footprint. The release includes a separate BF16 artifact for further adaptation and quantized variants suited to local inference.
For performance, NVIDIA reports 84 output tokens per second on an RTX Spark test using LiLiCorr speculative decoding and the AIPerf SPEED-Bench procedure. That is not a general guarantee for a GeForce desktop, different context lengths or higher concurrency. The model advertises text, image and video inputs, text output and up to 256K context, but the runtime instructions and KV-cache budget determine which combination is practical. An advertised 24GB weight fit also does not establish that all surrounding software and applications fit in that memory simultaneously.
Bolt is distributed under OpenMDW 1.1, which must be distinguished from Apache 2.0 and from NVIDIA's older models. Teams should select the exact 24GB artifact, check prompt/media handling, test speculative decoding with their own workloads and review their license obligations. Its intended advantage is access to capable local vision-and-tool workflows in a smaller weight budget; real speed, answer quality and safety remain use-case-specific and unverified here.
What this changes for the evidence layer
Check official NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB and -BF16 as separate variants with exact licenses, tensor formats, files and pinned repository revisions. A 24GB weight target does not certify a full 256K context window or target concurrency inside 24GB under every runtime. No new canonical model is verified or benchmarked by this news story.
NVIDIA Nemotron 3.5 Bolt 24GB technical report and official model card
This brief is based on the cited primary source. Performance, benchmark and comparative claims remain attributed unless Open Model Weights publishes an independent measurement.
Open source article ↗