Reflection has moved Beam from an announced open-weight project to an actual downloadable release. On October 5 the company described a 501-billion-parameter mixture-of-experts model and said final weights would follow later in the month. Its October 16 availability announcement is the new development: the official Hugging Face repositories now expose Beam 1.0 checkpoints under the Apache 2.0 license. That changes what developers can inspect and self-host today, rather than merely what the company plans to ship.
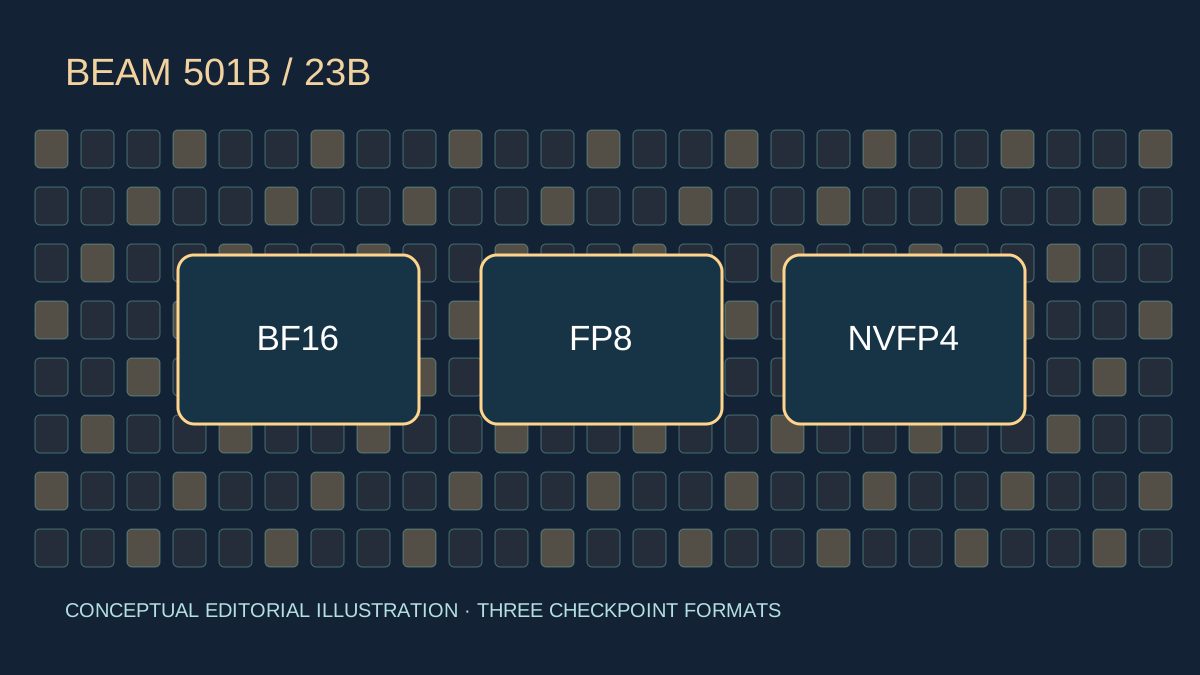
The official model card specifies approximately 501.3 billion total parameters and 23.4 billion active parameters, with text input and output and a context window of one million tokens. Beam targets software engineering, multi-step reasoning and tool-using agents. Its sparse expert architecture lowers active computation compared with a similarly sized dense model, but the complete model remains a large infrastructure commitment. The BF16 repository lists sharded Safetensors artifacts, and Reflection separately supplies FP8 and NVFP4 versions for other memory and serving profiles.
Reflection also publishes a DFlash2 speculative-decoding drafter designed to run alongside Beam. The drafter is not a standalone replacement for the 501B model: a serving system proposes tokens and Beam verifies them. The release post names integrations for Transformers, vLLM, SGLang and other serving or agent tools, alongside deployment and customization workflows. Those integrations expand practical access, but individual operators still need to check the specific runtime version and weight precision they intend to deploy.
The licensing distinction is especially relevant to teams comparing large open-weight systems. Apache 2.0 offers materially different reuse terms from custom licenses with service-provider thresholds, although deployment still requires safety, compliance and resource planning. Reflection reports competitive reasoning efficiency and coding results in its own evaluations. Open Model Weights does not convert those publisher measurements into independently verified scores. The registry consequence is clear: a previously preview-only model now has artifact-backed checkpoint candidates to verify.
What this changes for the evidence layer
This is a material status change from the 5 October preview already covered by Open Model Weights: Reflection now publishes model artifacts. Track Beam 1.0 BF16, FP8 and NVFP4 as distinct precision-specific checkpoint records and the DFlash2 speculative drafter as a separate supporting model, not another independent 501B base. Verify official revisions, shard manifests, config and Apache-2.0 license per artifact. Reflection's inference-efficiency comparisons are publisher claims; do not backfill independent performance or hardware-fit fields without measurements.
Reflection official 16 October Beam availability announcement
This brief is based on the cited primary source. Performance, benchmark and comparative claims remain attributed unless Open Model Weights publishes an independent measurement.
Open source article ↗