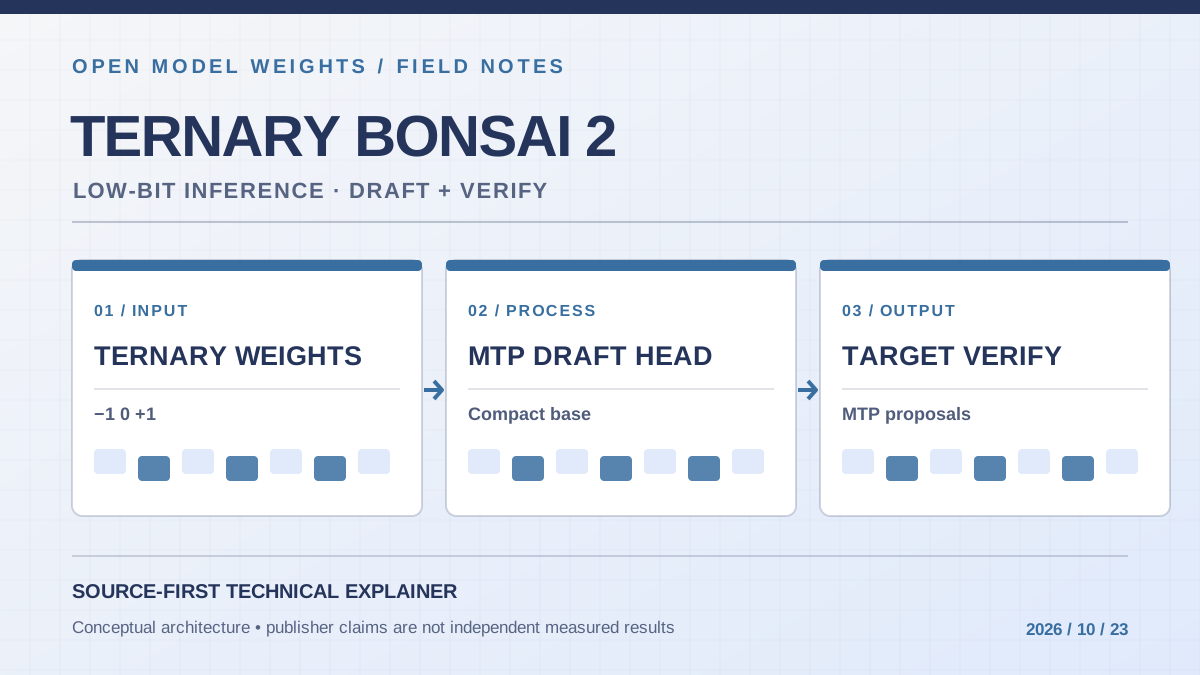
GreenBit AI has released a serving bundle for Prism ML's Ternary Bonsai 2 27B that combines unusually low-bit model weights with a model-specific multi-token prediction head. The new Hugging Face repository distinguishes two components: Prism's original ternary model assets, which GreenBit says are unchanged, and an optional draft head stored under mtp/. The repository declares Apache-2.0 and documents the bundled files and notices. This is principally an inference engineering release, not evidence that a new 27B base model was trained.
Ternary weights represent values using minus one, zero and plus one, enabling compact packing. The additional head proposes several future tokens; the target model then verifies those proposals before accepting output. That matters because speculative decoding can reduce repeated full-model passes without simply trusting a smaller model's answers. GreenBit describes distilling the head on Bonsai-generated prose, code, chats and coding-agent examples, beginning from a Qwen3.8-27B multi-token prediction component.
In its own matched Mac Studio M3 Ultra test, GreenBit reports 114 decode tokens per second on short prompts with its gbx-lm 0.8.2 implementation, against 42 for Prism's referenced MLX runtime. On a DGX Spark it reports 62 tokens per second and 5.9 GB of loaded model memory, compared against the configurations listed in its repository. These are publisher-conducted measurements, not independent Open Model Weights results. Prompt length, decoding mode, exact quantization, kernel versions and cache policy can change the comparison.
The practical takeaway is a concrete, inspectable approach to faster local 27B inference with a distinct optional acceleration component. Teams can test the OpenAI-compatible local endpoint, compare draft-head-on versus off using identical prompts, and measure end-to-end throughput, output equality, memory and latency on their own hardware. Do not generalize the reported ratios to all GPUs or assume that a compact weight file represents peak application memory.
What this changes for the evidence layer
This GreenBit bundle is a separate publisher repository and has not been selectively source-verified into the canonical model table; news coverage does not create a new model record.
GreenBit AI official Ternary Bonsai 2 27B gbx model card
This brief is based on the cited primary source. Performance, benchmark and comparative claims remain attributed unless Open Model Weights publishes an independent measurement.
Open source article ↗